


Every business that monitors prices, tracks competitors or builds a dataset from the open web eventually asks the same question: write a scraper against the page structure, or hand the job to an AI model that reads the page the way a person would. Both approaches are in production use in 2026, and the honest answer is that most teams end up running both, not picking one.
This guide compares traditional, selector-based scraping with AI-driven extraction on cost, resilience and maintenance, and walks through a real project where our team chose one over the other under a tight budget.
How Traditional Web Scraping Works
Traditional scrapers target a predictable HTML structure, a table, a product grid, a list of headlines, using CSS selectors or XPath expressions. Three variants cover most business use cases:
- Static scraping: targets a fixed template and works well for price and product monitoring on pages that rarely change structure.
- Dynamic scraping: uses a headless browser to render JavaScript-driven pages, the approach needed for most e-commerce and social sites.
- API-based extraction: pulls structured data directly from a site's own API when one exists, the fastest and most reliable option, but far from universal.
Where Traditional Scraping Breaks
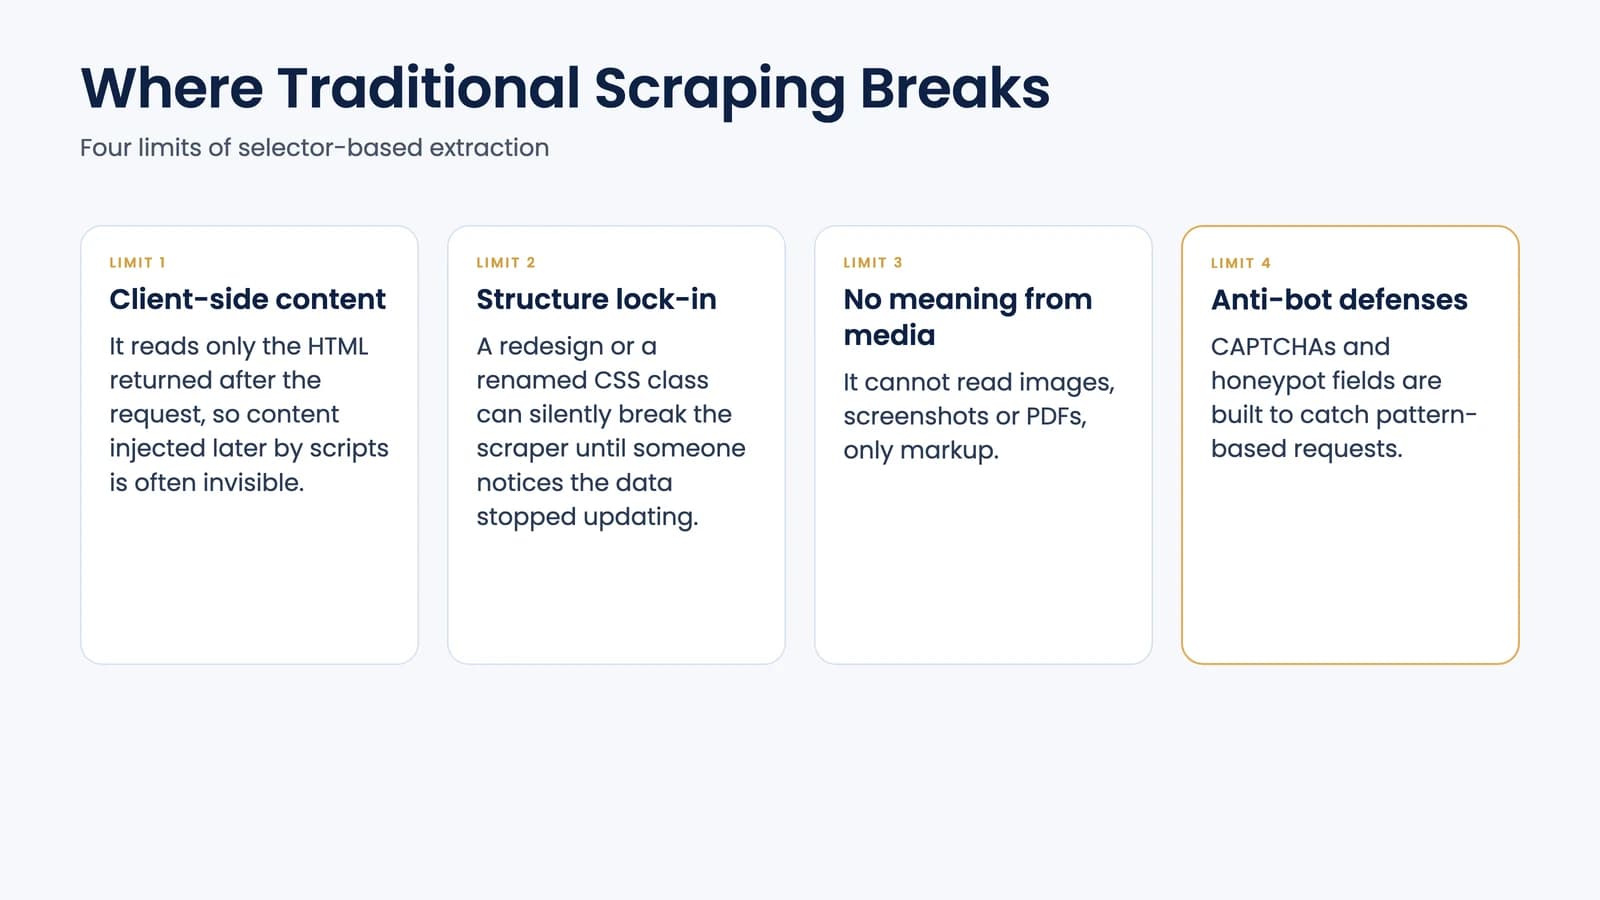
- It reads only the HTML returned after the request, so content injected later by client-side scripts is often invisible to it.
- A selector is tied to one page structure, so a redesign or even a renamed CSS class can silently break the scraper until someone notices the data stopped updating.
- It cannot read meaning out of images, screenshots or PDFs, only out of markup.
- Anti-bot defenses such as CAPTCHAs and honeypot fields are built specifically to catch pattern-based requests.
How AI-Driven Scraping Works
Instead of matching a fixed selector, an AI-based extractor learns what the target data looks like semantically, a price, a date, a product name, and finds it regardless of which HTML tag or class currently holds it. When a site's markup changes but the data is still on the page, the extractor keeps working, which is the main practical advantage over a hand-written selector.
| Traditional scraping | AI-powered scraping | |
|---|---|---|
| Resilience to layout changes | Breaks when a selector no longer matches | Keeps working if the data is still on the page |
| Unstructured content | Cannot read images, PDFs or screenshots | Can extract text and structure from them |
| Cost per record at scale | Low once built | Higher: every extraction can call a paid model |
| Maintenance | Grows with every site redesign | Lower once a source is stable, per 2025-2026 industry reporting |
What changed since this comparison was last written is less the core trade-off, which has held for several years, and more the maturity of the tooling on the AI side: models now handle longer pages reliably, multimodal models can read a screenshot or a PDF table directly instead of needing a separate OCR step, and several vendors now ship pre-built agents that retry a failed extraction automatically.
The Real Costs on Both Sides
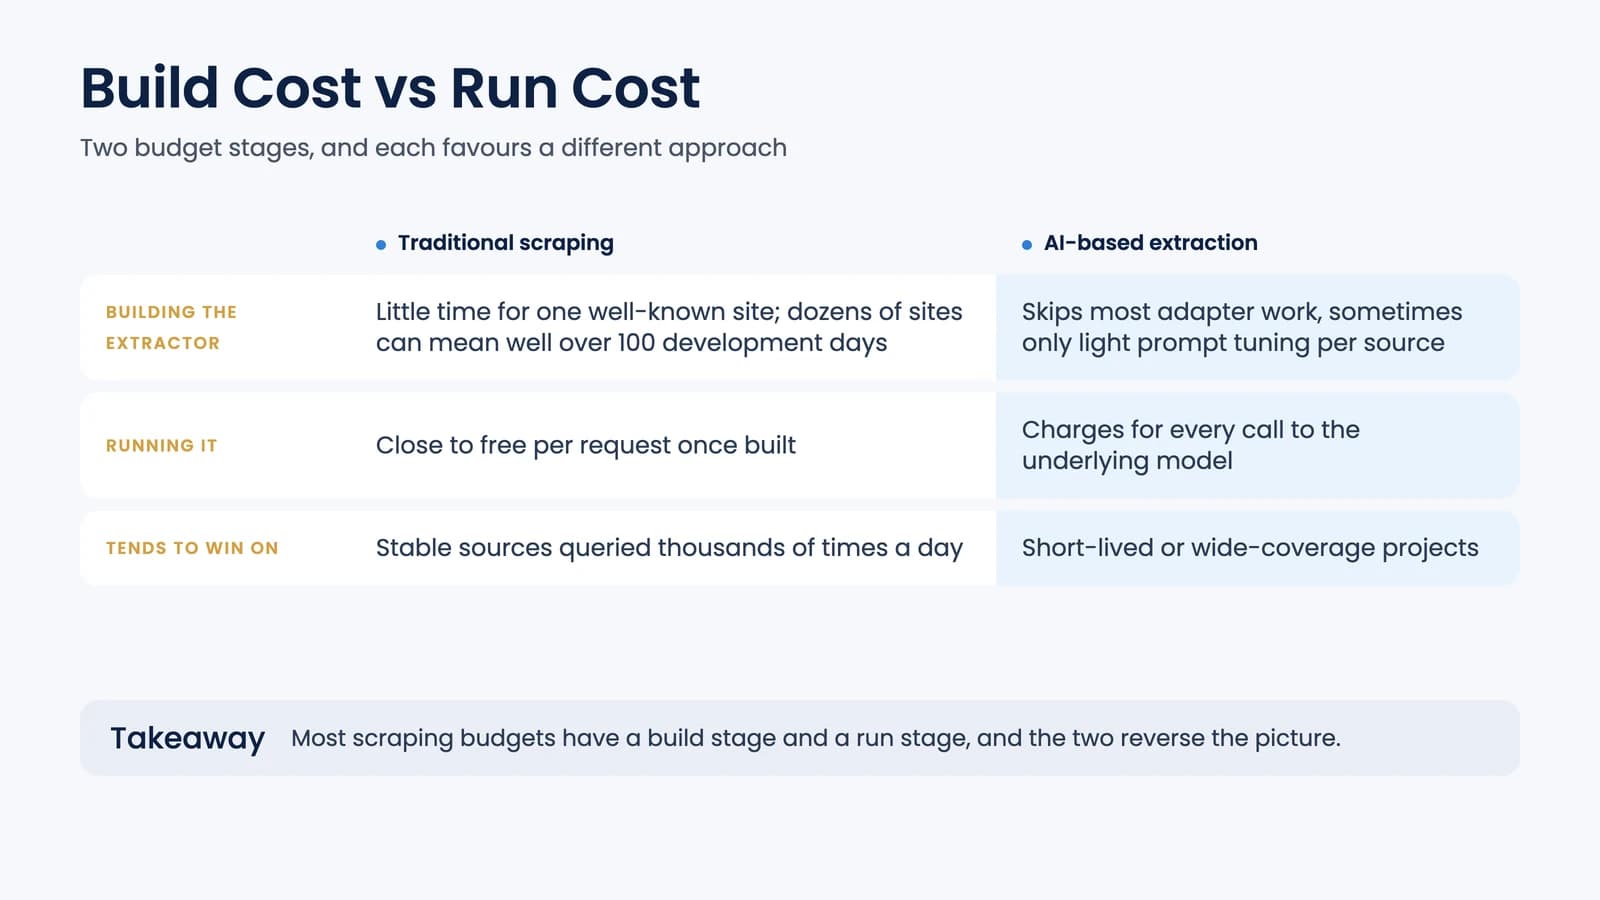
Most scraping budgets have two stages: building the extractor, and running it. A traditional adapter for one well-known site takes little time, but a project pulling data from dozens of sites can mean well over 100 development days, each one needing its own selectors and its own fix whenever the target redesigns. An AI-based extractor skips most of that adapter work, sometimes needing only light prompt tuning per source, which is why it tends to win on short-lived or wide-coverage projects.
The second stage reverses the picture. A finished traditional scraper is cheap to run, close to free per request. An AI-based pipeline charges for every call to the underlying model, and industry estimates for 2026 put AI extraction at 10 to 100 times the cost per record of a deterministic scraper, depending on the model and the amount of content per page. For a source you will query thousands of times a day with a layout that barely changes, that gap adds up fast.
Risks to Weigh Before You Automate
- Accuracy: an AI extractor can misread or invent a field under ambiguous markup, so output still needs spot-checked validation before it reaches a downstream system.
- Privacy and legal exposure: scraping personal data or bypassing a site's access controls can trigger data protection and computer-access laws that vary by jurisdiction; this is an operational and legal review question, not a purely technical one.
- Vendor dependency: an AI pipeline ties your data collection to a model provider's uptime, pricing and policy changes in a way a self-hosted scraper does not.
The 2026 Default Is Hybrid
Most production data pipelines in 2026 run both approaches side by side: deterministic scraping or a structured API for the handful of sources hit constantly, and AI extraction reserved for the long tail of one-off or fast-changing sources where writing and maintaining a dedicated adapter would not pay for itself. If the scraped data itself is feeding other AI systems, such as a pricing model or a chatbot, it is worth reading our wider look at AI use cases in finance, since the data-quality problems are the same ones that show up downstream.
A 4IRE Case: Scraping a Dozen Marketplaces on a Grant Budget
A client with a fixed grant budget needed product data from more than a dozen online marketplaces, each with its own structure, for a proof-of-concept data analysis tool. Building and maintaining a dozen-plus custom adapters was not realistic for the budget, so we used AI extraction as the primary method, which cut the manual adapter work to close to nothing.
We tested several models, including Anthropic's Claude 3 Sonnet, Mistral 7B Instruct and Meta's Llama 3 8B Instruct, across three hosting options (Hugging Face, Vertex AI and Amazon Bedrock), and compared them on speed, accuracy and output consistency. Mistral 7B Instruct on Bedrock gave the best balance for this project and became the production choice, though the output still needed manual adjustment to match our front end's expected structure. On this project, with its many sources and tight timeline, AI scraping worked out more cost-effective than building adapters for every marketplace would have been.
Choosing the Right Approach
A short checklist for making the call, before you build either kind of scraper or bring in our AI development team to do it:
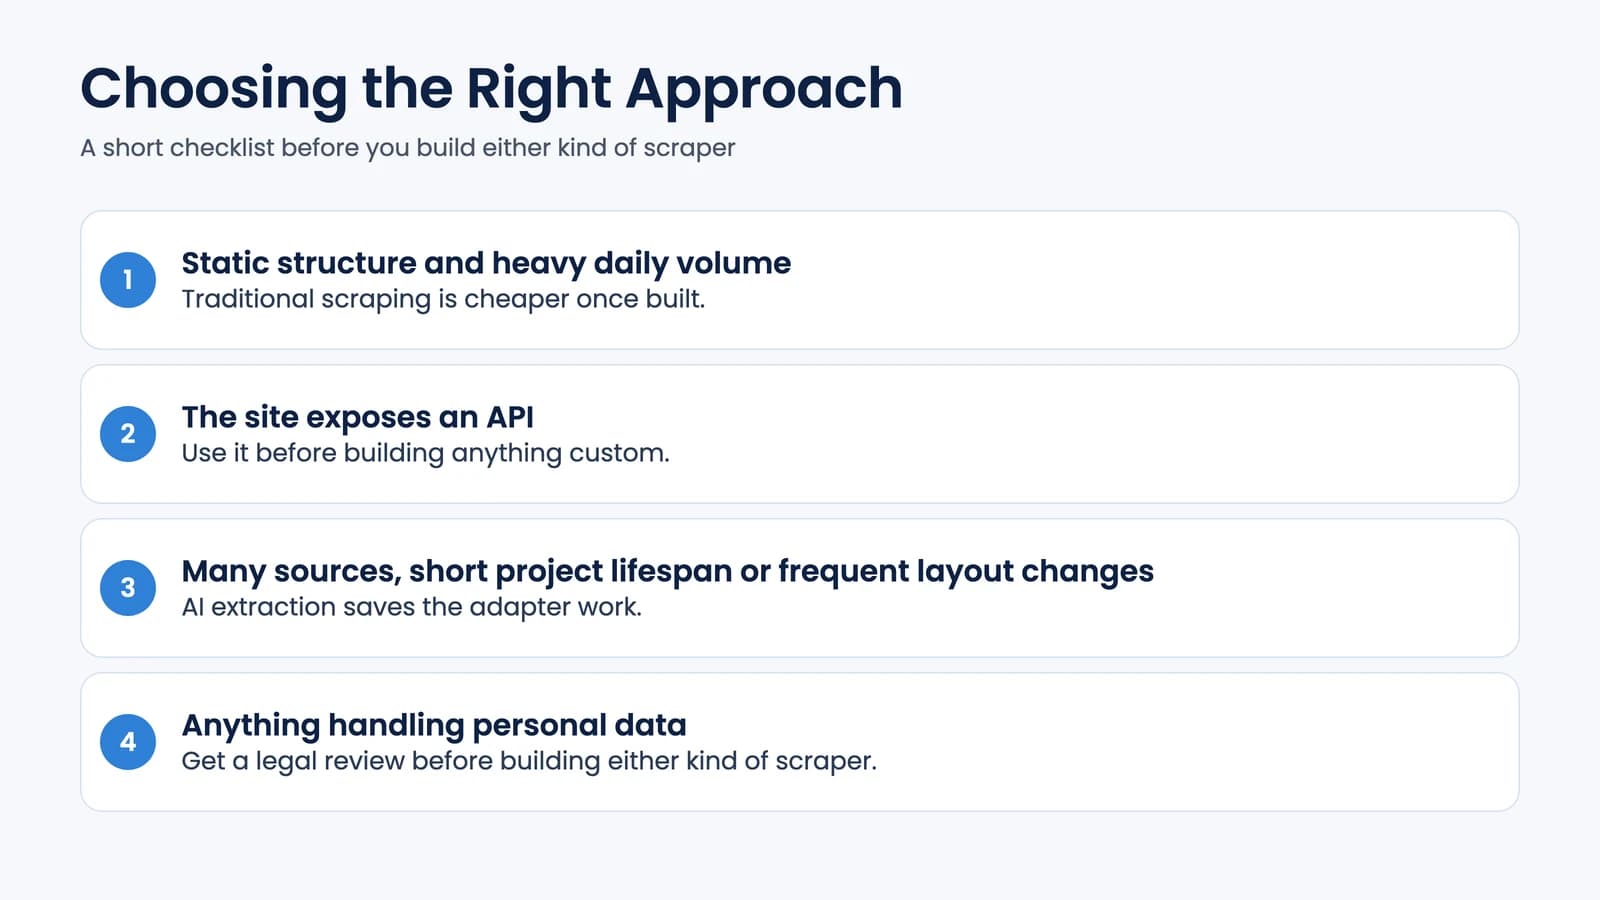
- Static, rarely-changing structure and heavy daily volume: traditional scraping is cheaper once built.
- A site exposes an API: use it before building anything custom.
- Many sources, short project lifespan, or frequent layout changes: AI extraction saves the adapter work.
- Anything handling personal data: get a legal review before building either kind of scraper.
Conclusion
Traditional scraping is still the cheaper, more predictable choice once a source is stable and worth the adapter investment. AI-driven extraction earns its higher per-record cost on sources that change often or are not worth custom-building for. Most real pipelines in 2026 use both, matched to each source rather than to a company-wide policy.
Learn more from us
 28 Sept 2026
AI in Finance: How AI Solutions Reshape the Financial Sector
AI in finance in 2026: fraud and AML, credit scoring, GenAI assistants, agentic payments, EU AI Act rules and how to start an AI project.
Olena Petrashchuk
 01 Oct 2026
AI, IoT and Blockchain Convergence: Where It Actually Works in 2026
AI, IoT and blockchain each solve a different problem. Here's where combining them works today, including DePIN, and where the idea still falls short.
Vladislav Malynovskyi
 AI29 Sept 2026
AI Agents in Crypto: 7 Use Cases for Exchanges, DAOs and DeFi
Where AI agents actually run in crypto today: exchanges, DAOs, launchpads and DEXs, what guardrails they need, and how to scope a pilot.
Vladislav Malynovskyi
Building a data pipeline that needs scraping at scale?
Our team has shipped both traditional and AI-driven extraction pipelines, including under tight grant and startup budgets. Let's scope which approach fits your sources.
FAQ
It targets a specific HTML structure with CSS selectors or XPath, using static scraping for fixed templates, headless browsers for JavaScript-driven pages, or a site's own API where one exists.
It cannot read content added after the page loads unless it renders JavaScript, breaks when a selector no longer matches a redesigned page, cannot read images or PDFs, and struggles against anti-bot defenses.
An AI-based extractor looks for data semantically, not by a fixed selector, so it keeps working when a site's markup changes, and it can read unstructured content such as screenshots and PDFs that a traditional scraper cannot.
Per record at scale, usually yes: industry estimates for 2026 put AI extraction at 10 to 100 times the cost of a deterministic scraper. It tends to win instead on projects with many short-lived or fast-changing sources, where it avoids most of the adapter-building cost.
Teams pulling data from many different, loosely structured sources, or sources that change layout often, see the clearest benefit. Teams scraping a handful of stable, high-volume sources usually do better with a traditional or API-based scraper.